

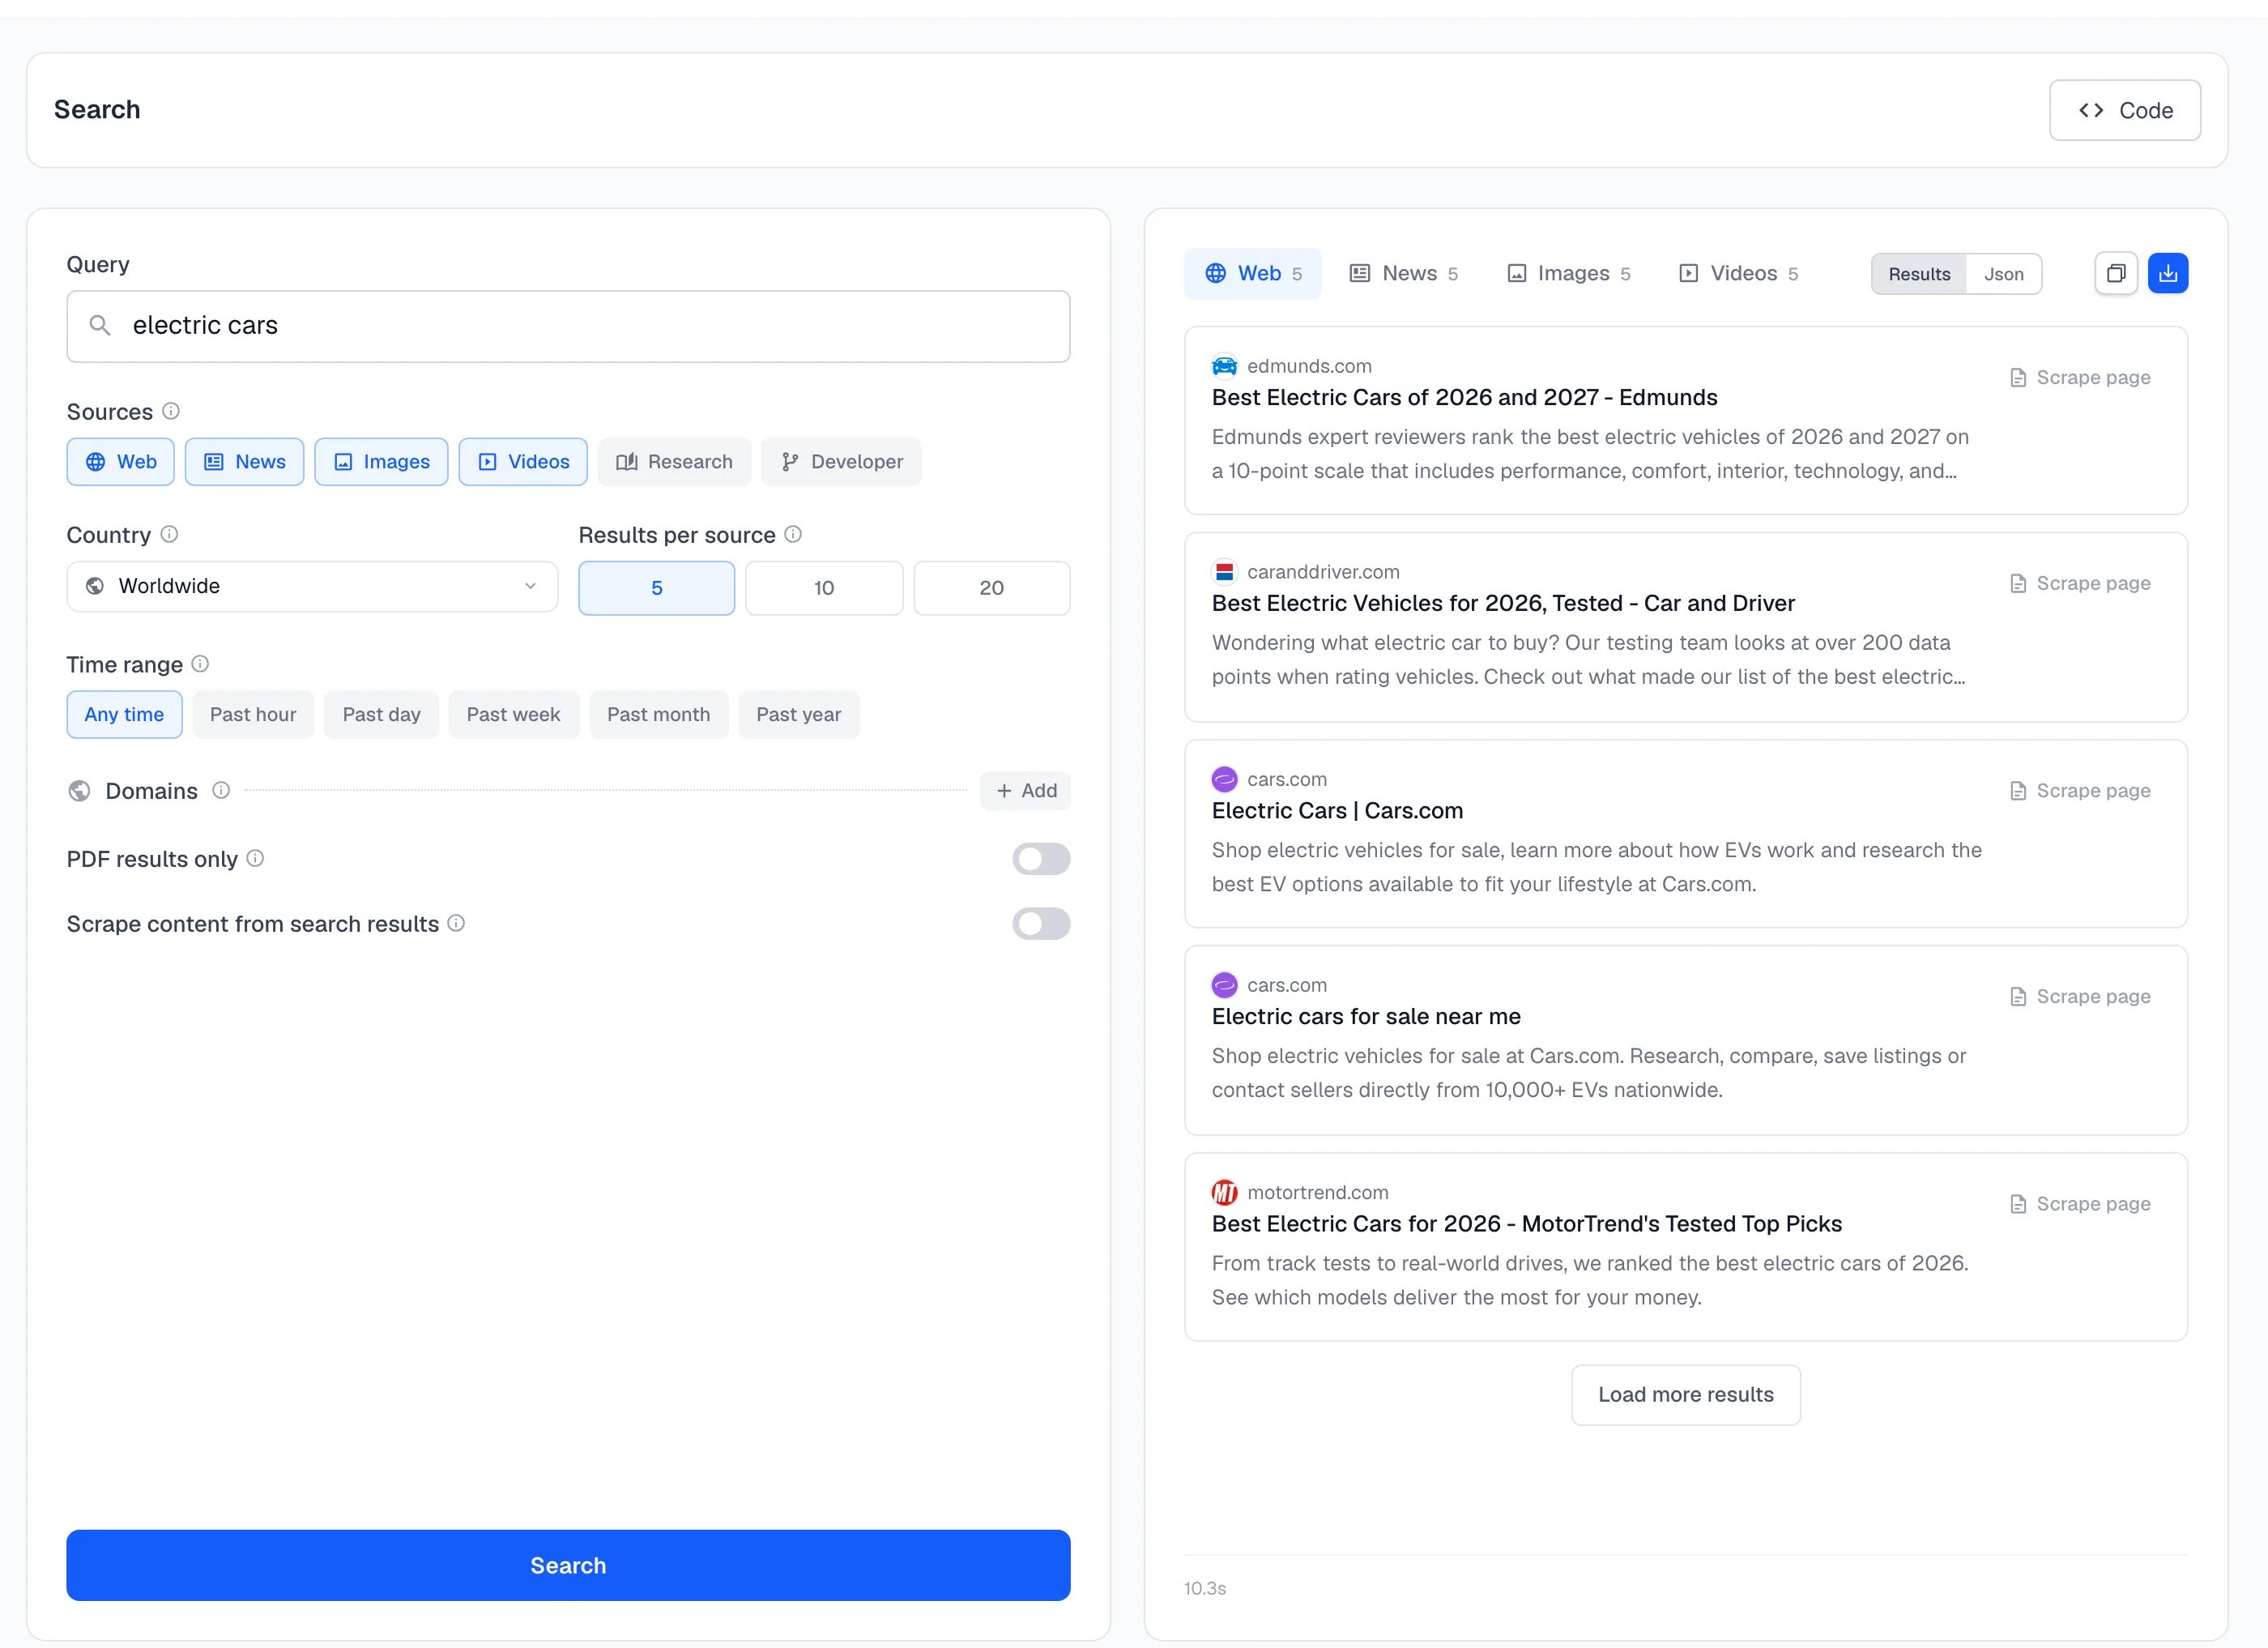
Search and Scrape solve different problems. Search answers “what results exist for this query?” Scrape answers “get me the content of this specific page.” If you already know the URL, use Scrape. Search is for discovery.
Run a search in the dashboard
Open the Search playground. The form on the left holds every option. Only the query is required.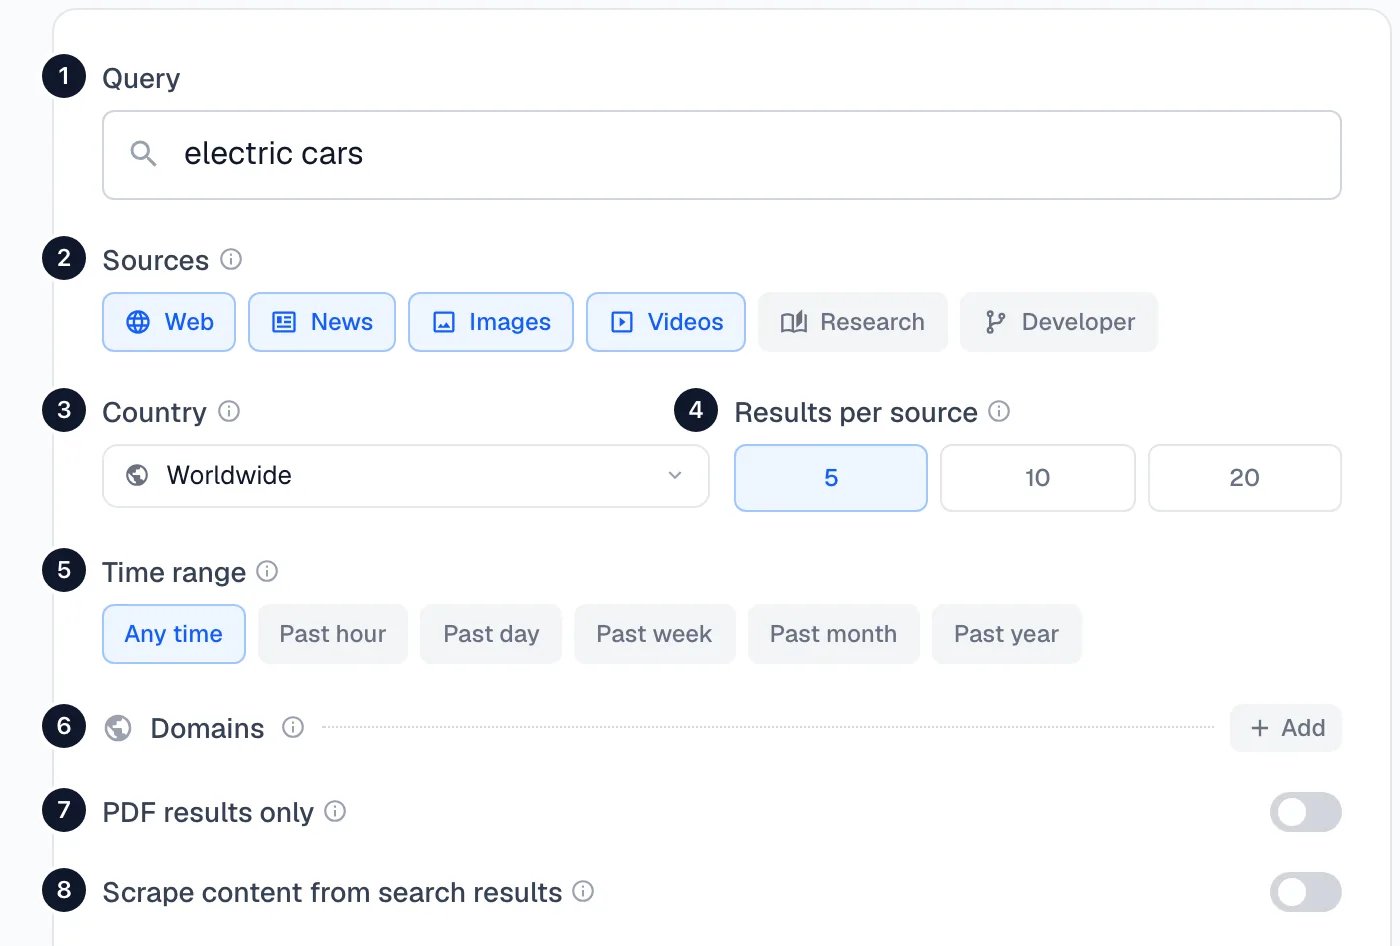
- Query. Type what you are looking for, the way you would on any search engine. Questions and short keywords both work.
- Sources. Choose the kinds of results you want: Web, News, Images, Videos, Research (academic papers) or Developer (GitHub issues and pull requests). You can pick several, and each runs on its own, so one source coming back empty does not affect the others.
- Country. Makes the search look like it comes from that country, so you see results the way someone there would. Leave it on Worldwide for generic results.
- Results per source. Choose 5, 10 or 20. This is per source, so four sources at 10 returns up to 40 results. A lower number is faster and can cost less. See what a search costs.
- Time range. Favor recent results: past hour, day, week, month or year. It is a bias toward newer results and not a hard cutoff, because not every result carries a reliable date.
- Domains. Click Add to restrict results to certain sites (Include) or to leave some out (Exclude). You can only use one mode at a time.
- PDF results only. Limits web results to PDF files, for things like annual reports and filings.
- Scrape content from search results. Also fetches the page content for each result. See Scrape content from results.
Include or exclude domains
Click Add under Domains, choose Include or Exclude, then type one or more domains separated by commas. Domain filters apply to the web, news, images and videos sources, not to research or developer.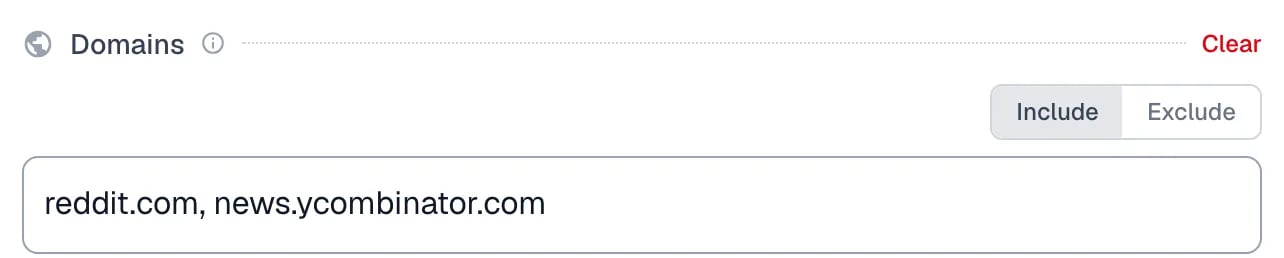
Scrape the pages behind the results
Turn on Scrape content from search results and choose how many of the top results to read: the first 3, the first 5, or All, which means up to the first 10.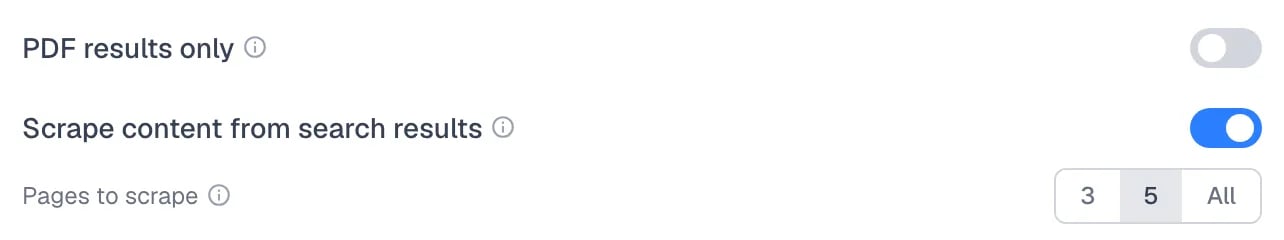
Read your results
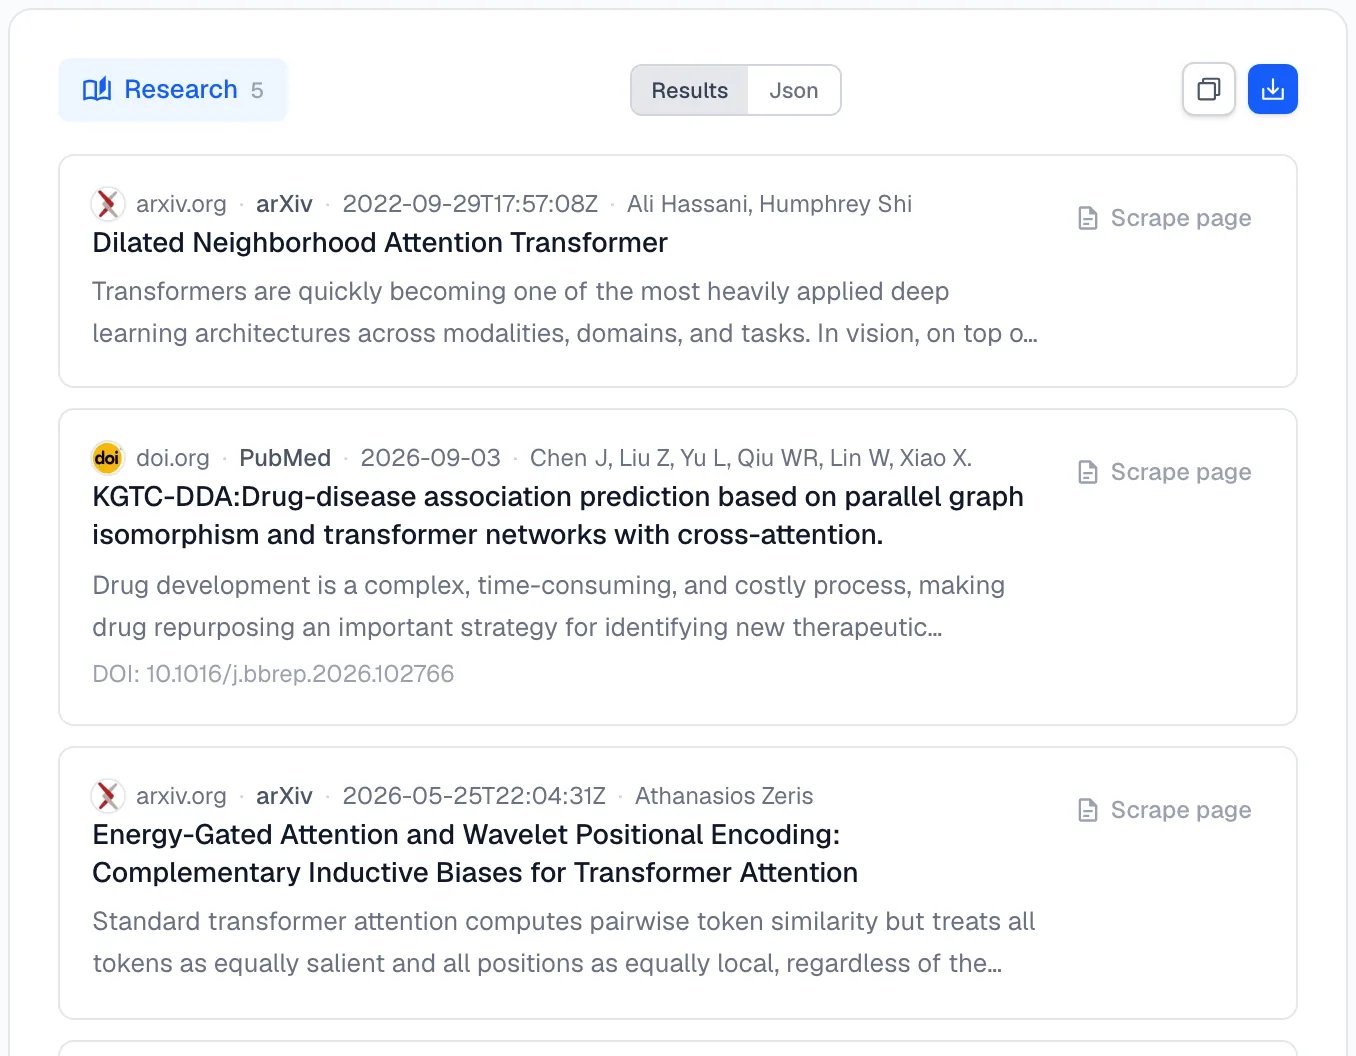
Results appear on the right, grouped into a tab for each source you chose. The number beside each tab is how many results it holds. Switching tabs never mixes data.
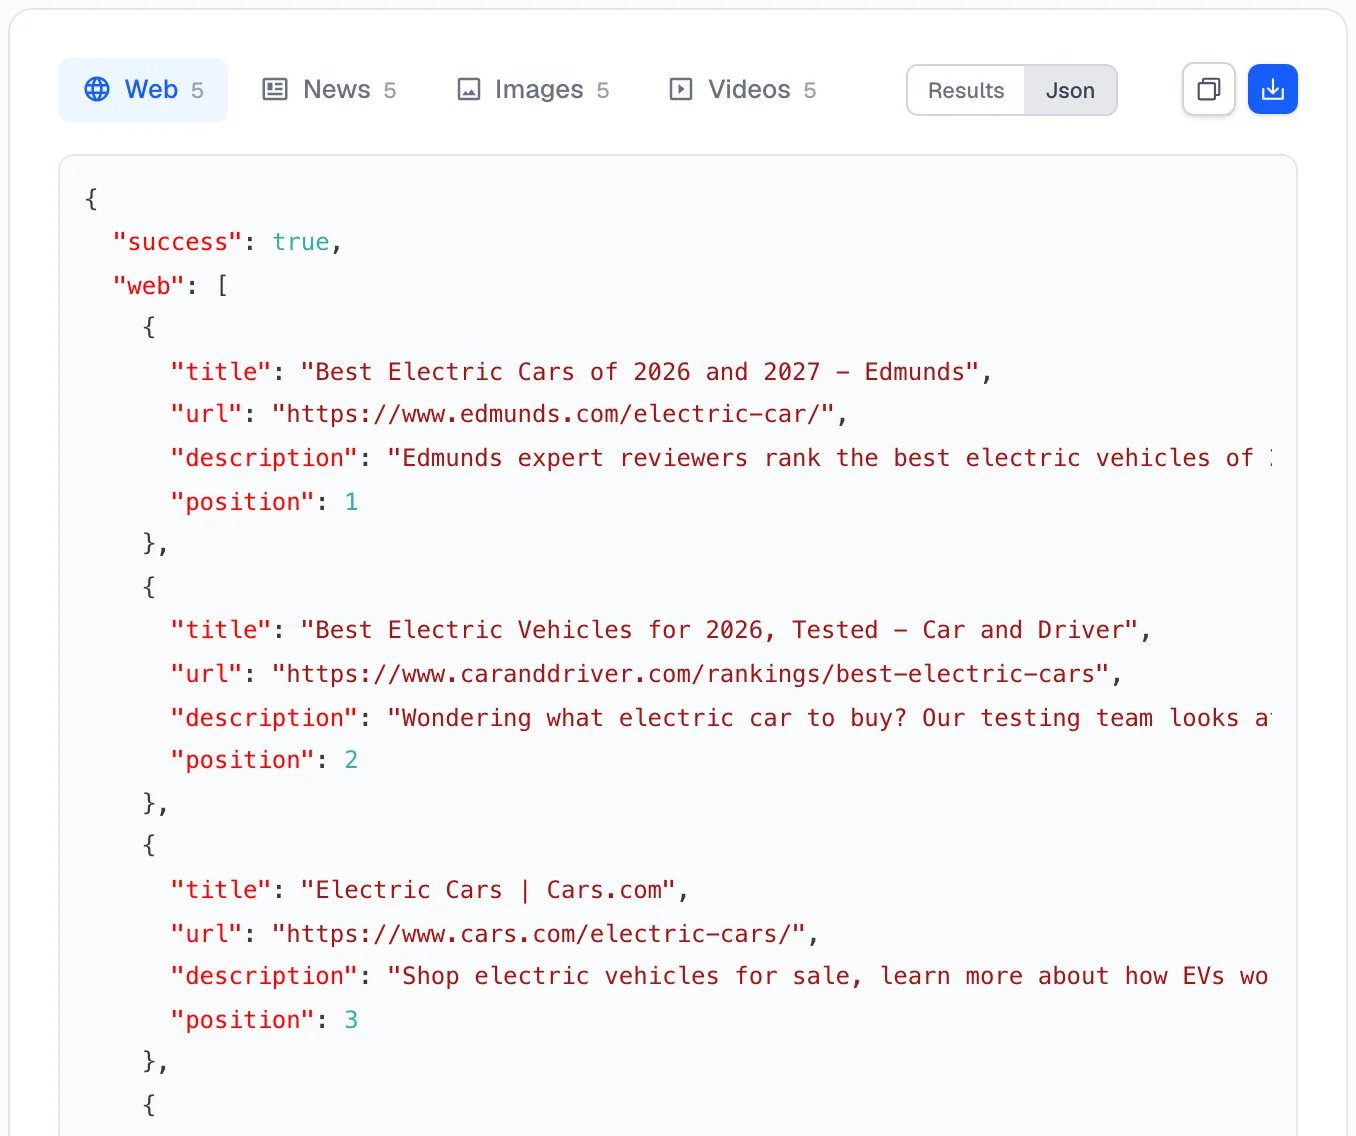
- Results and Json. Results is a readable list of cards. Json shows the raw response for the tab you are on, ready to paste into your own code.
- Copy. Copies what is on screen for the active tab.
- Download. Saves what is on screen as CSV or JSON. On the Images tab it downloads the actual image files as a ZIP instead.
- Time. The time the search took appears at the bottom of the results.
The result cards
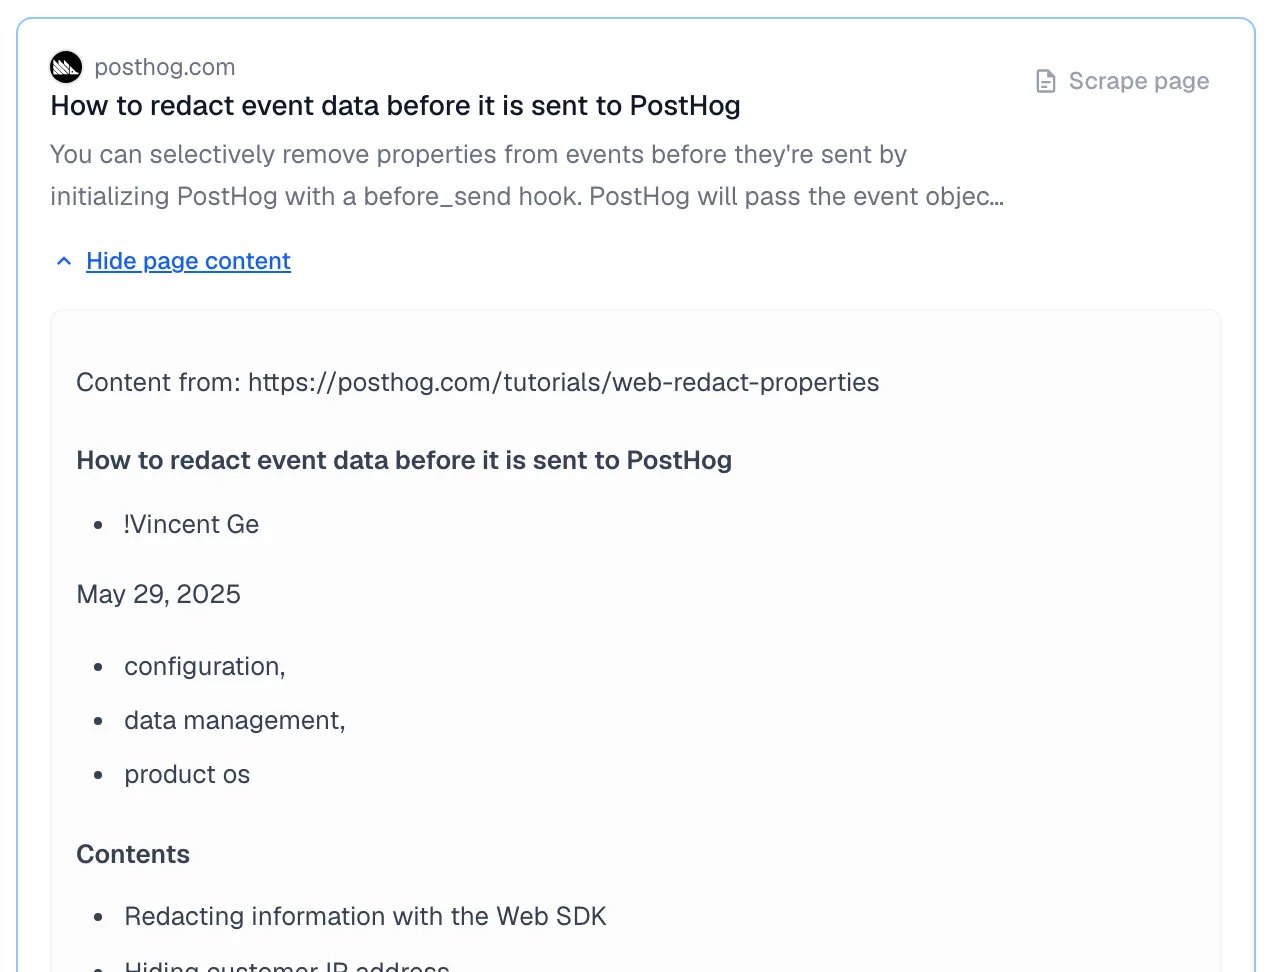
Each web, news and research result is a card with the site, title and description. The Scrape page link on a card opens the Scrape playground with that URL filled in, which is the way to go when you need AI extraction, a schema or a screenshot for one specific page.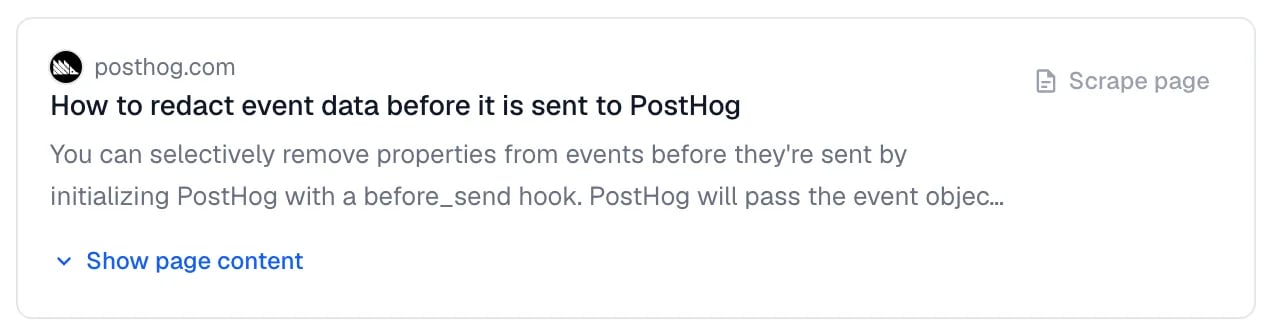
The JSON view
What each source returns
Dates are given as the source reported them, so news may say “12 hours ago” while videos and papers use a full date.
Images, research and developer results
The Images tab shows a grid. Download on this tab gives you the pictures themselves as a ZIP, and you can also save images one at a time.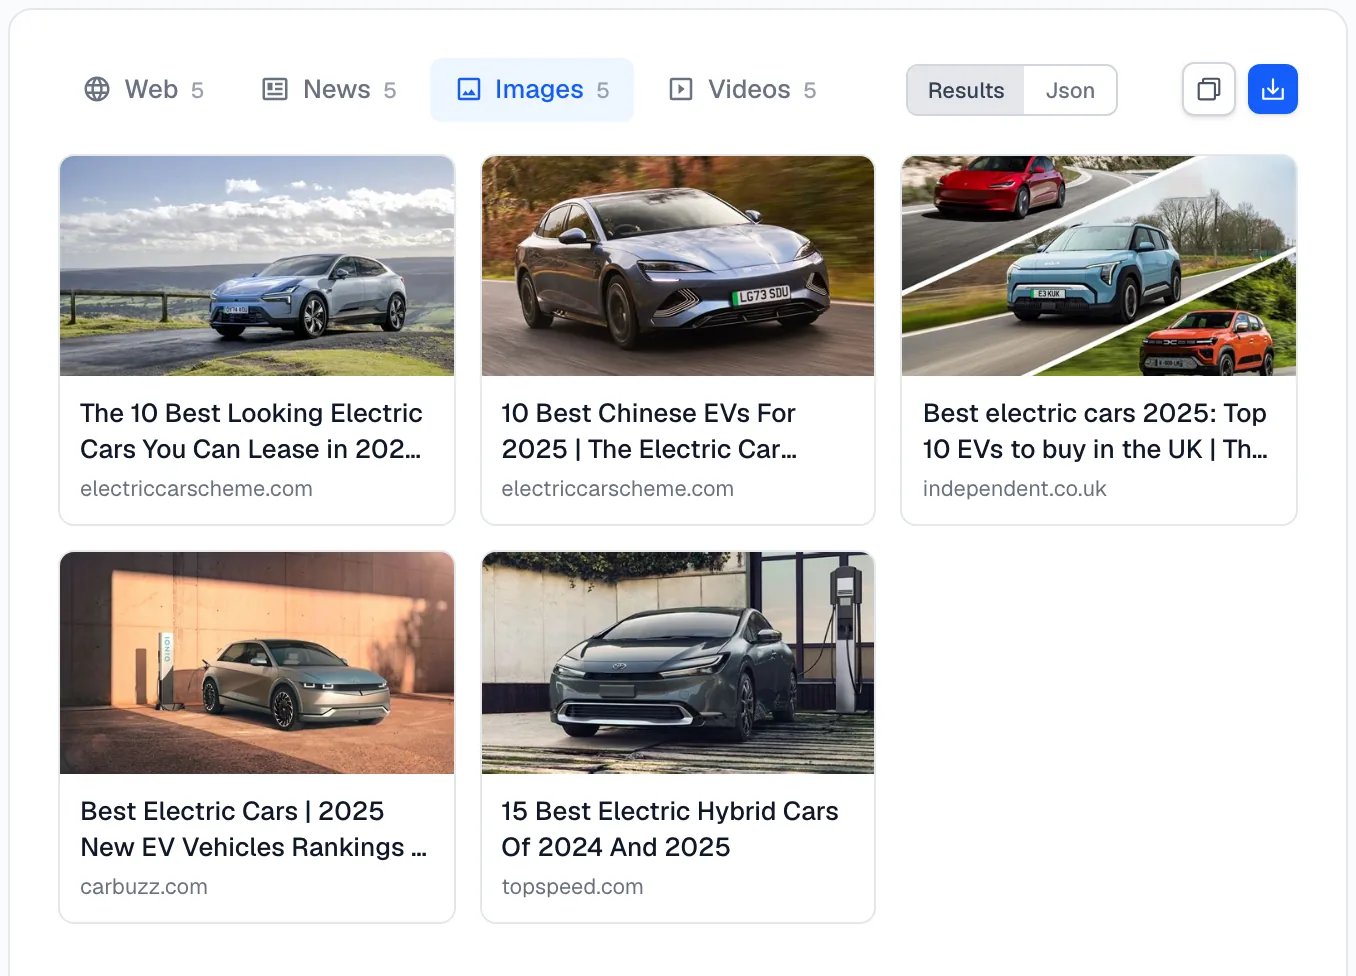
memory leak is:issue repo:vercel/next.js.
Load more results
At the bottom of a tab, Load more results fetches the next page for that tab. It continues exactly where the last page ended, and the positions keep counting up. Each extra page is a new search and is charged like one.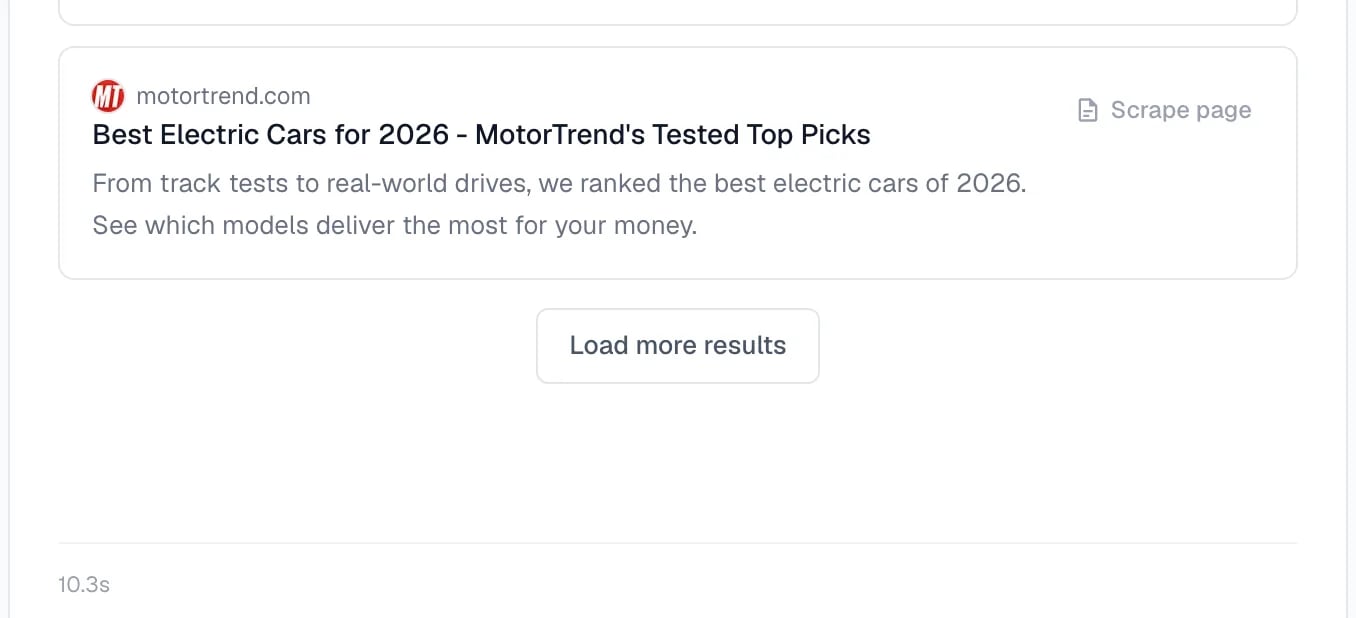
Related searches and quick answers
For some web searches, Spidra also returns related searches, or a quick answer such as a currency conversion. When they exist they appear above the web results. Not every query has them, so do not rely on them being there.Scrape content from results
Turn on Scrape content from search results and Spidra fetches each result’s page in the same request, so you do not need a separate scrape step.- Clean markdown. Content comes back as plain readable markdown with navigation, headers and footers removed. There is no prompt or schema to set.
- You choose how many. The first 3, the first 5, or up to 10 with All. Fewer pages is faster and cheaper.
- It takes longer, on purpose. The search waits until every page has been read before it shows anything, so a search with page content takes as long as its slowest page. A plain search finishes in seconds, while one that fetches pages can take around half a minute.
- Failures are quiet. A page that cannot be fetched is left without content and the rest of your results are unaffected.
- Want more than markdown? For a schema, an extraction prompt or a screenshot, use the Scrape page link on that result to open it in the full Scrape playground.
What a search costs
Search costs 1 credit per 10 results, per source, rounded up. A source that returns nothing costs nothing.
The full rules are in How credits work, and you can see what each search used in your search logs.
Run the same search from code
Click Code at the top right of the playground and Spidra writes the request for you, using the options currently set in the form. Pick JavaScript, Python or curl, choose which of your API keys to use, and copy it.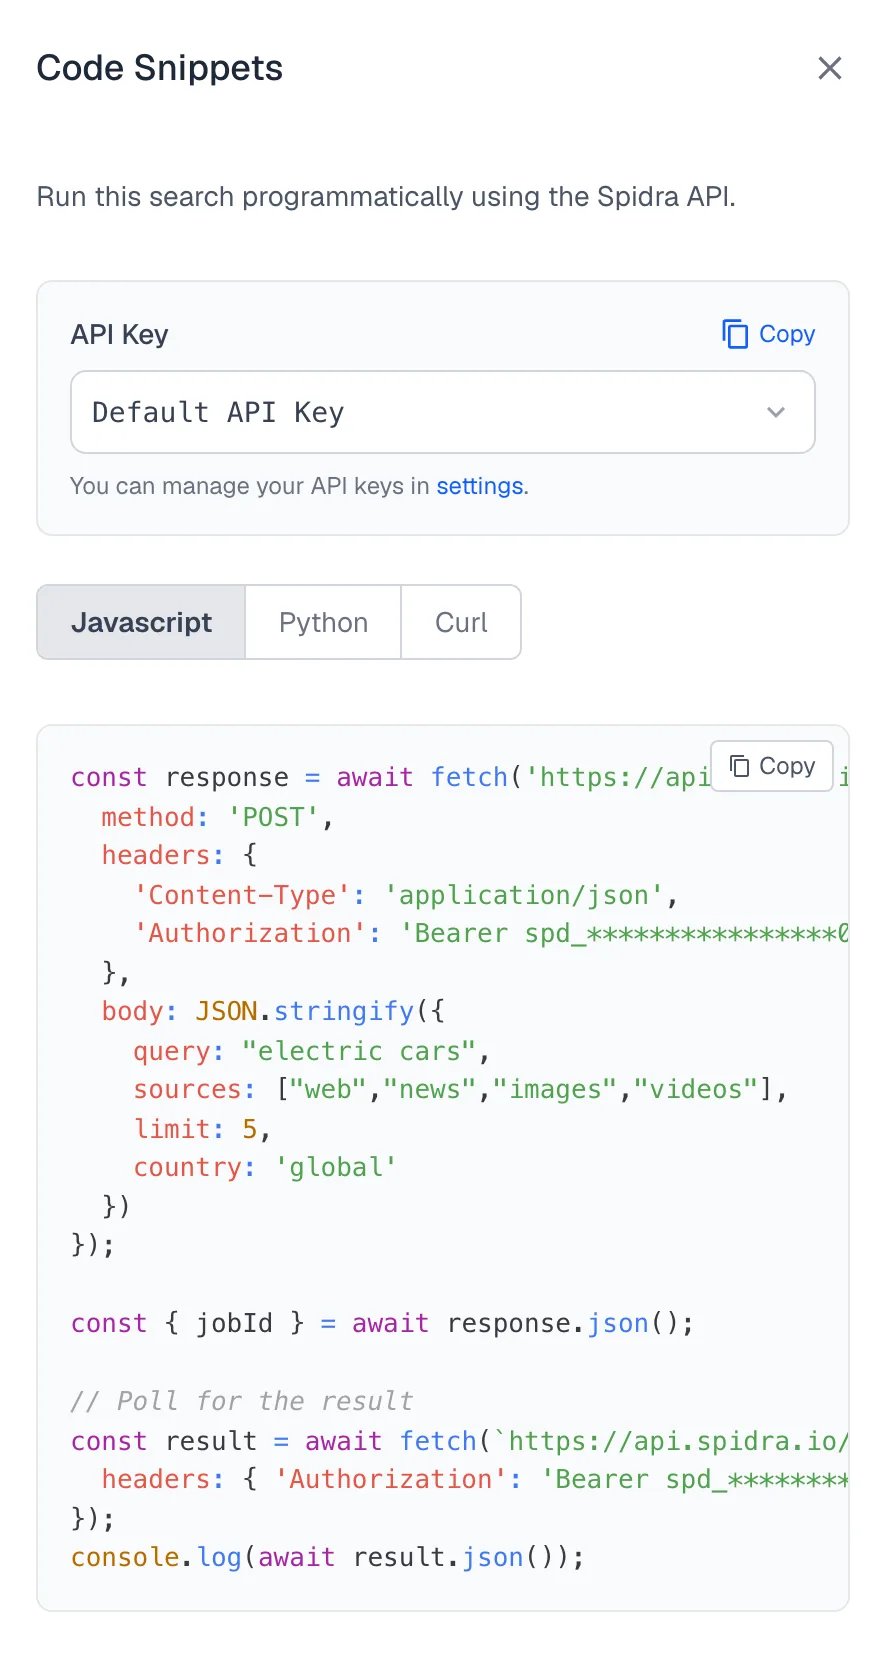
"wait": true, the API answers straight away with a job ID and you poll for the result. The SDKs do that for you. With wait, a plain search returns its results in the same call, and if it takes longer than about 20 seconds it falls back to the job ID. See Get the result without polling.
Here is the shape of the response, trimmed to two results:
scrapeOptions (scrape_options in Python). It is the code version of the Scrape content switch:
Use Search from an AI assistant
The Spidra MCP server gives AI assistants such as Claude, Cursor and VS Code aspidra_search tool. Once it is connected, you can ask for search results in plain language:
“Search for the best espresso machines of 2026 and summarize the top 3.”The assistant fills in the same options you have in the playground: the query, sources, how many results, country, time range, domains, PDF only and page content. A search that takes longer than the assistant’s first wait finishes in the background, and the assistant checks on it with
spidra_check_search_status. The credits come from your balance exactly as they do for any other search, so what a search costs applies here too.
Setting up a client is covered on the MCP server page.
If your client connects to the hosted server and you do not see
spidra_search in its tool list, run the server on your own machine with npx -y spidra-mcp. That version always includes Search.More you can do
- Pages of results. Continue a search with
pageTokens, which keeps the positions counting up. See Pagination. - Time range.
timeRangefavors recent results. See Time range. - Research and developer sources. Search arXiv, PubMed, bioRxiv and medRxiv papers, or GitHub issues and pull requests. See Research and developer sources.
- PDF search.
filetype: "pdf"limits web results to PDFs. It works best on topical queries such as “climate change report”. Very narrow queries can come back empty, and a search that finds nothing costs nothing. See PDF search. - Bigger images. Add
imagesize:1920x1080orlarger:1920x1080to an image query to favor large images. It is a preference and not a guarantee. See HD image search. - Search history. Every search is saved with its query, sources, filters and the credits it used, in your logs and through the Search Logs API.
Search, Scrape and Crawl
A common pattern is to run a search with page content turned on, which is often all you need in one call. Need a schema or a screenshot for one result? Click its Scrape page link.
Submit a Search
Full API reference for the search endpoint
How credits work
What a search costs and how to estimate it
Tips
- Start with just web. It is the quickest source and covers most queries. Add the others when you need them.
- Search before you scrape when you are unsure of the URL. Finding the right page first is usually faster than guessing one.
- Set a country when location matters. Local news, regional pricing and “near me” queries all depend on where the search appears to come from.
- Keep limits modest. Most uses do not need 20 results, and a smaller number is faster and cheaper.
- Treat time range and country as hints. They shape results but do not filter them strictly.