Add documents
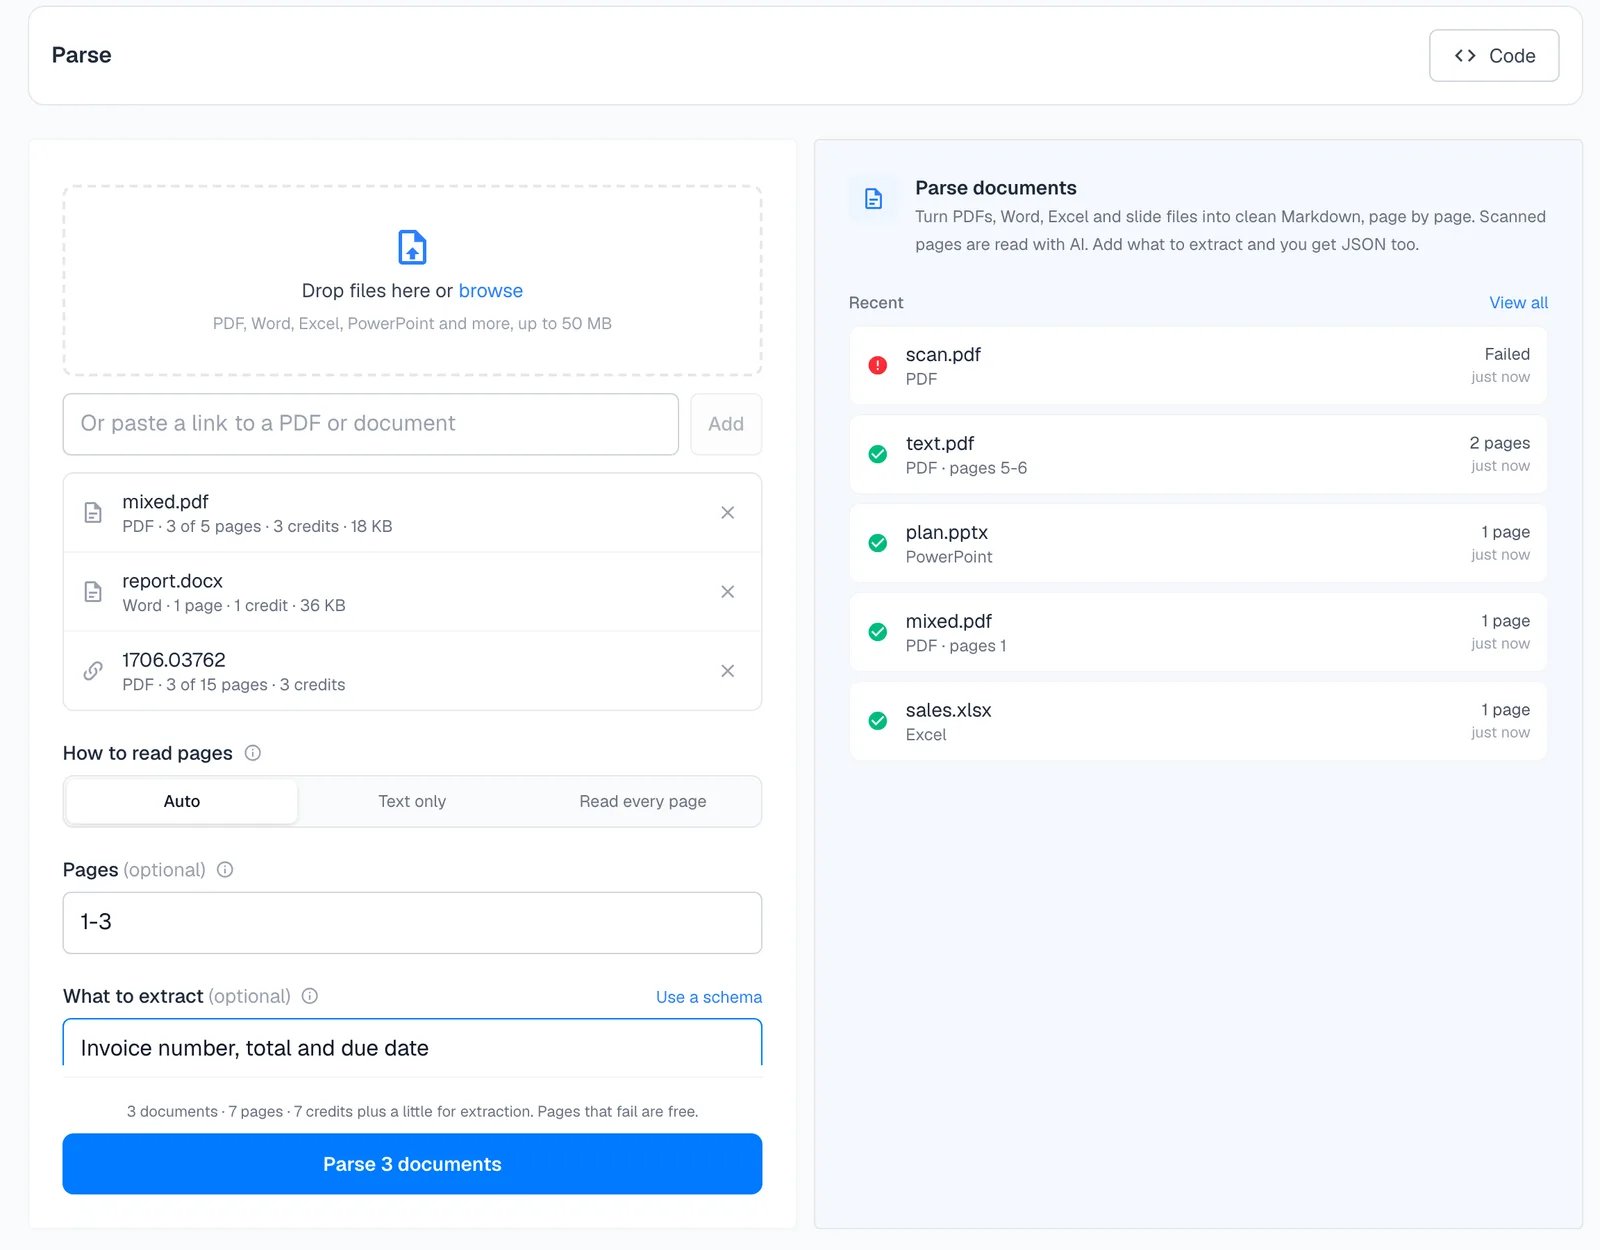
- Upload: drop files on the page or click browse. Up to 50 MB each in the dashboard. The API also takes prepared uploads up to 500 MB.
- Link: paste a link to a PDF or document and press Add.
Options
- How to read pages. Auto reads each page’s own text and uses AI only for scans. Text only never uses AI and skips scanned pages. Read every page uses AI on all pages, for documents whose text layer is unreliable.
- Pages. Parse only some pages of each PDF, such as
1-5,1-3, 8or10-(page 10 to the end). Costs update as you type. - What to extract. Describe the fields you want, or define a schema, and the result includes them as JSON.
The result
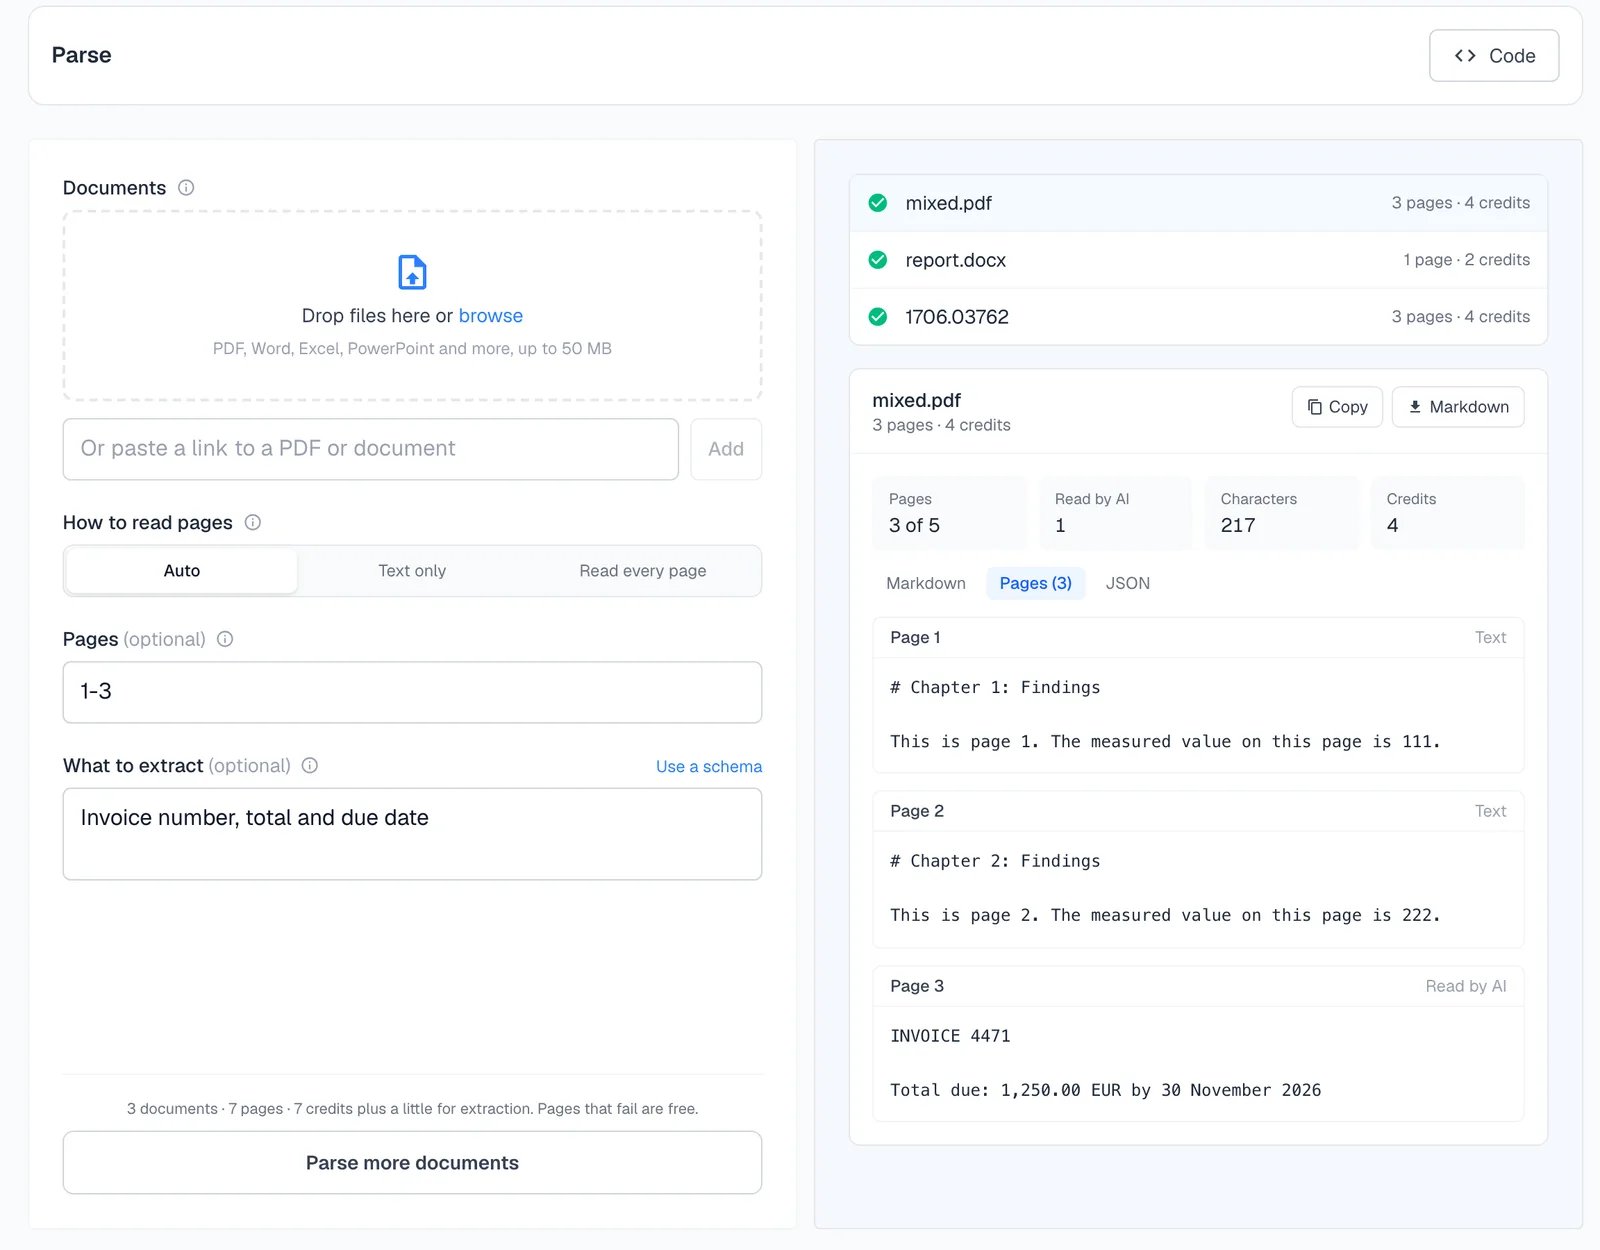
- Markdown: the whole document.
- Pages: each page on its own, marked Text or Read by AI.
- JSON: the extracted fields, when you asked for some.
1-3 and the instruction Invoice number, total and due date:
What it costs
1 credit per page parsed, whether the page was read from its text or with AI. Word, Excel and other formats count one page per 3,000 characters of output, at least one. Extraction adds AI token credits. Pages that can’t be read and documents that fail are free. See How credits work.Privacy
Uploaded files are kept for 24 hours so you can parse them again with other options, then deleted. Delete one sooner with DELETE /parse/files/{fileId}. Parsed results are kept like your other logs.Parse with code
Parse API
Every option, response field and error
Scrape
For web pages rather than documents